
Skip to content

Category: Ohne Kategorie

Published: Uses of Metaverse Recordings in Multimedia Information Retrieval

Visual for the publication Uses of Metaverse Recordings in Multimedia Information Retrieval

Published – Yet another First: scored the first article in the first issue of the new @multimedia journal by MDPI. It has been a month online, but yikes, it was a busy month :)

Metaverse Recordings (XR) can be made in the technical space of a computer. As part of our research, we explored the opportunities that recordable data can bring to Multimedia Information Retrieval.

Thanks again to my co-authors for your support Prof. Dr.-Ing. Stefan Wagenpfeil, Ingo Frommholz, and Matthias Hemmje.

Metaverse Recordings (MVRs), screen recordings of user experiences in virtual environments, represent a mostly underexplored field. This article addresses the integration of MVR and Multimedia Information Retrieval (MMIR). Unlike conventional media, MVRs can include additional streams of structured data, such as Scene Raw Data (SRD) and Peripheral Data (PD), which capture graphical rendering states and user interactions. We explore the technical facets of recordings in the Metaverse, detailing diverse methodologies and their implications for MVR-specific Multimedia Information Retrieval. Our discussion not only highlights the unique opportunities of MVR content analysis, but also examines the challenges they pose to conventional MMIR paradigms. It addresses the key challenges around the semantic gap in existing content analysis tools when applied to MVRs and the high computational cost and limited recall of video-based feature extraction. We present a model for MVR structure, a prototype recording system, and an evaluation framework to assess retrieval performance. We collected a set of 111 MVRs to study and evaluate the intricacies. Our findings show that SRD and PD provide significant, low-cost contributions to retrieval accuracy and scalability, and support the case for integrating structured interaction data into future MMIR architectures.

DOI: 10.3390/multimedia1010002

Leave a Comment
Monatsupdate August

Dissertation Update

Updates an der Publication-Front:

Das Paper Integration of Metaverse and Multimedia Information Retrieval von der ICSA ist nun in der ACM Digital Library verfügbar

Zum 256 Metaverse Recording Dataset habe ich ein Paper geschrieben, dass auf der ACM Multimedia 2024 angenommen wurde! Hier gehts zum OpenReview

Mit einem Studenten habe ich ein Paper zur Avatar Erkennung geschrieben. Dies ist als Preprint verfügbar.

Research Topics:

Image generation: Aktuell exploriere ich mit Bildgenerierung von Metaverse Daten für die Result Presentation. Experimente laufern mit Stable Diffusion 3 (medium und large). Beide Modelle sind sehr interessant, vor allem wiel die Textgenerierung in den Bildern schon sehr gut läuft, wenn auch nicht perfekt.

Weitere Experimente laufen mit Obejct Detection und Sprachanalyse. Detectron 2 bietet eine gute Umsetzung von R-CNN Varianten, eine Alternative zum bekannteren YOLO Netzen. Auch die neuen YOLO Versionen (v10 , April oder Mai veröffentlicht) wäre eine Untersuchung auf Metaverse Content Wert. Also auf die Todo Liste. Dazu gehe ich in die Sprachanalyse, ich bin sher begeistert von der Qualität von Whisper und untersuche nun die Toxizität in den Metaverse Aufnahmen.


Skill2Lead

Skill 2 Lead: Ich arbeite weiter an Coaching Inhalten für Fachkräfte, die sich zur Führungskraft entwickeln wollen oder es jüngst wurden. Als Sideproject aktuell nicht die Top-Prio.

Sonstiges

Juli: 145,6 km Rad gefahren. Nicht sooo viel, aber immherin summiert es sich auf 638,2 km in diesem Jahr. Wird mal wieder Zeit für 3-stellige Touren :)

VeloWear App: Kann man mit KI eine App bauen, ohne Programmierkenntnisse zu haben? Ja, soweit geht das schon. Ich habe den ersten Teil einer YT-Serie gestartet. Die App ist schon im Testflight Mode, Part 2 kommt bald.

1 Comment

Updates KW 25

Hey Leute, vergangene Woche war vollgepackt mit spannenden Projekten und Aktivitäten. Hier ein kurzer Überblick:

Tech-Projekte:

  1. RAG mit Langchain: Ich habe endlich Zeit gefunden, Retrieval-Augmented Generation (RAG) mit Langchain zu testen. Die Evaluierungen waren recht aufschlussreich, und ich bin begeistert von den Möglichkeiten, die sich dadurch für meine Projekte eröffnen.
  2. llama.cpp: Parallel dazu habe ich mich mit llama.cpp beschäftigt. Es ist faszinierend zu sehen, wie effizient diese Implementierung große Sprachmodelle auf Consumer-Hardware laufen lässt.
  3. Whisper OpenAI Plugin: Ein echtes Highlight war die Integration des Whisper OpenAI Plugins für Information Retrieval. Ich habe damit gleich ein 256 Metaverse Dataset indexiert – die Ergebnisse sind vielversprechend!

Sonstiges:

  • Sport: Trotz des vollen Terminkalenders habe ich es geschafft, regelmäßig Sport zu treiben. Es hilft ungemein, den Kopf frei zu bekommen.
  • Kleinanzeigen: Ich habe mich endlich dazu durchgerungen, ein paar Sachen zu verkaufen, die ich nicht mehr brauche. Überraschend, wie viel sich da über die Zeit ansammelt!


Das war’s erstmal von mir. Wie war eure Woche so? Bis bald!

Leave a Comment

Bucket List Achievement: My first scientific paper

I am beyond excited to share with you all a significant milestone in my academic journey: the publication of my first scientific paper in the MDPI Big Data and Cognitive Computing Magazine! As someone deeply passionate about the fields of computer science, this accomplishment is not only a testament to my dedication, but also a realization of a long-time goal. In this blog post, I’d like to share the story behind my research and the path that led to this achievement.

Leave a Comment

My 2022 in review

The end is near, I mean the end of the year. I want to look back and reflect on my personal year.

Achievements

First public conference talk(s): At this year’s FrOSCon, I was invited to give two conference talks – on one day. That was my first time at a public conference and it went very well.

Published first print article: I could land a spot in a German IT magazine, “IT-Spektrum”. It was a long dream of mine to do this and I was very happy that it worked on the first try.

Published a web article on GraphQL: Together with Oliver I wrote an article about GraphQL Federation in microservice architectures.

Leave a Comment

4 Tips for development of Alexa Skills

In the last weeks, I have developed some Alexa Skills for different purposes. It is really cool to develop the skills with the Alexa developer console. Building and testing the dialogue model is fairly easy. But at some points, you may encounter some problems like me. Therefore, I would like to share some tips with you to improve the user experience of a skill significantly.

Tip 1: Use Default Slot Types

Let’s start with a simple topic. If possible, use the provided slot types from Amazon, like Amazon.FOOD or AMAZON.NUMBER. These Slots have a huge set of data in the background. They are already optimized for a good NLP understanding. Doing this on your own is a lot of work and fine-tuning the model. Save yourself many hours and use what Amazon provides you.

Tip 2: Use a proxy for local development

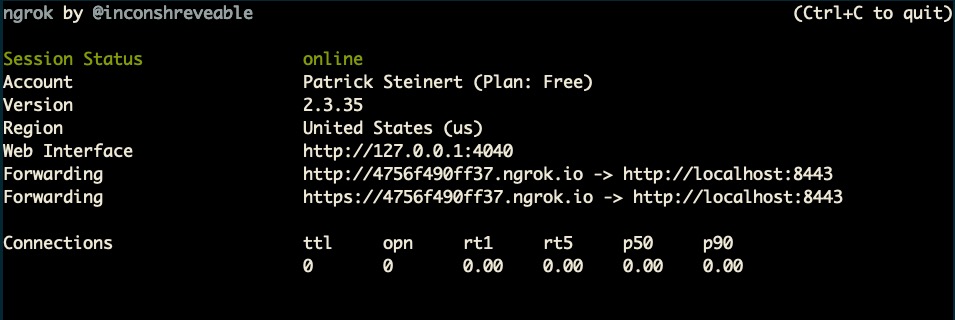
There are different ways to implement the logic for the service: AWS Lambda or (self-hosted) endpoint services. If you develop endpoints services, you need to redirect the requests from the Alexa skill to the development instance, usually running on the local machine. An important thing is, the service needs to provide a valid TLS certificate. The easiest way to get it running is a web-proxy system like ngrok. Ngrok routes requests via a public web URL to your local development instance. And the best thing is, it has an option to provide a valid Wildcard-TLS-Endpoint which will be accepted by Alexa. This saves you a heck of time to set up anything equivalent with DynDNS and creating certificates. ngrok - a good tool for developing Alexa Skills

Tip 3: Answer not only use-case questions

During the development of Alexa skills, you work a lot through the questions (utterances) you have in mind with regard to the use case. But, think about your users. They can just interact with your app by asking questions. They can not click through a mobile app or website to search and find things they need. It’s important to be prepared for simple and general questions such as:

  • “What are the opening hours?”
  • “What is the address of a store?”
  • “What is the maximum of items I can order?”

Think about how your customer will ask questions. Ask your friends to try the skill and listen to their natural type of questions and commands. You can also log questions in the FallbackIntent to find out what real people say.

Tip 4: Test Alexa Skill dialogue with many people

This tip continues the thoughts of the previous. Many people will formulate questions and commands differently. Since the skill is usually used by many people, you need to be prepared for different types of utterances. Add as many sample utterances as you can to improve the user experience for the skill.

These 4 tips will improve the user experience of your Alexa skill. Do you have any further tips? Let me know in the comments.

2 Comments

x

Nachlese: Froscon 20 Vortrag “AI-First Softwareentwicklung – aber Open Source”

Comments closed

x

Nachlese: Froscon 20 Vortrag “AI-First Softwareentwicklung – aber Open Source”

Comments closed

x

Nachlese: Froscon 20 Vortrag “AI-First Softwareentwicklung – aber Open Source”

Comments closed

x

Nachlese: Froscon 20 Vortrag “AI-First Softwareentwicklung – aber Open Source”

Comments closed